Why the distinction matters
Once an organisation outgrows reports built directly on its ERP and a collection of spreadsheets, it needs a place to combine, clean and store data from multiple systems for analysis. Three terms dominate the conversation: data warehouse, data lake and lakehouse. Vendors use them loosely, so confusion is understandable — yet each approach solves a slightly different problem.
The data warehouse
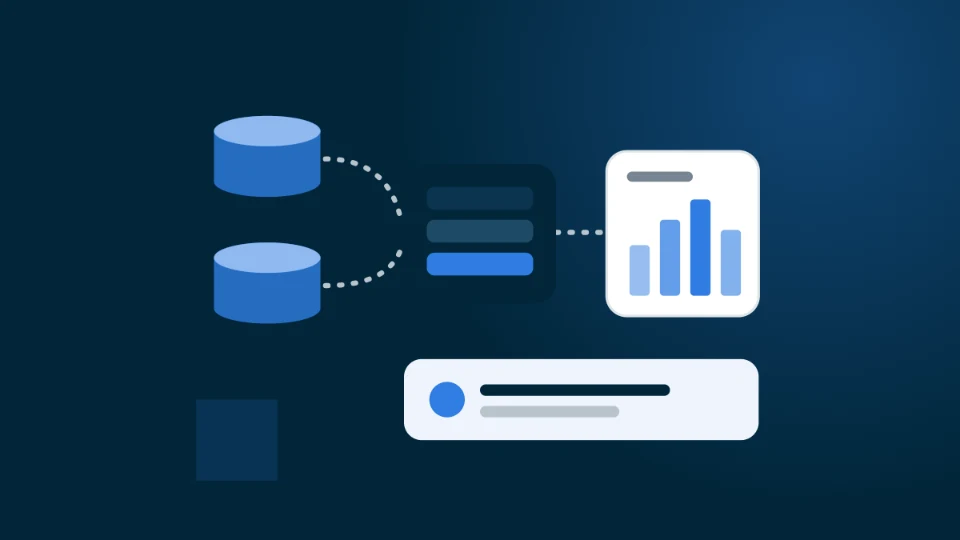
A data warehouse is a structured database designed for analysis and reporting. Data is cleansed and shaped into a predefined model before it is stored, typically a star schema with fact tables (sales, orders) and dimension tables (customers, products, dates). This is known as schema-on-write: the structure is defined up front.
Strengths:
- fast, predictable query performance for reports,
- consistent metric definitions — a single version of the truth,
- mature tooling and SQL skills that most teams already have.
Weaknesses:
- less flexible for new data types and experimentation,
- structural changes require rework of the loading processes.
The data lake
A data lake is low-cost storage that holds data in its original form: tables, logs, JSON, images, system exports. Structure is applied only when data is read — schema-on-read.
Strengths:
- stores anything, at scale and at low cost,
- well suited to data science and machine learning,
- lets you capture data before you know exactly how you will use it.
Weaknesses:
- without governance, a lake quickly becomes a "data swamp" where nothing can be found,
- weaker support for transactions and data quality,
- data must be processed further before it is useful for everyday reporting.
The lakehouse
A lakehouse aims to combine the best of both. Data sits in inexpensive lake storage, but in a table format with transactional guarantees — for example Delta Lake on top of Parquet files. The same data can then serve SQL queries for reporting as well as Python or Spark workloads for advanced analytics.
Data is typically organised in layers, often called the medallion architecture:
- Bronze — raw data as it arrives from source systems,
- Silver — cleansed and conformed data,
- Gold — curated, reporting-ready models, frequently as star schemas.
Platforms such as Microsoft Fabric and Databricks follow this approach.
Side-by-side comparison
| Data warehouse | Data lake | Lakehouse | |
|---|---|---|---|
| Data structure | predefined | flexible | layered, tabular |
| Data types | structured | any | any |
| Reporting | excellent | poor without processing | excellent in the Gold layer |
| Data science | limited | excellent | excellent |
| Governance effort | moderate | high (risk of sprawl) | moderate |
ETL or ELT?
Architecture also shapes how data is loaded. Traditional warehouses use ETL: transform first, then load. Lakehouses and modern cloud warehouses more often use ELT: load raw data first and transform it inside the platform. ELT is more flexible because the original data remains available for new questions.
What to choose for business reporting
For most mid-sized organisations whose goal is reliable reporting from ERP, CRM and other operational systems:
- Structured data and well-defined reports? A classic warehouse or the Gold layer of a lakehouse will serve you equally well.
- Unstructured data, logs or data science on the horizon? A lakehouse gives you room to grow without re-platforming.
- A raw data lake on its own is not suitable for reporting.
More important than the architecture label are a solid data model, clear metric definitions and accountable data owners.
Bottom line
A data warehouse is structured and fast, a data lake is flexible and cheap, and a lakehouse combines both in a layered design. For reporting, what matters is the analysis-ready layer, not the marketing term. Choose based on the data you have today and expect tomorrow — and on the people who will run the platform.
If you are planning a data warehouse or a move to a lakehouse, explore our data warehouse implementation services — we design an architecture that fits your data.